Self-learning and aPKC
on Monday, July 13th, 2026 8:37 | by Björn Brembs
In this paper on Aplysia operant conditioning, Fred Lorenzetti and colleagues find that PKC activity is upstream of an Adenylyl cyklase making cAMP (with other hypotheses dimmed). In Drosophila, we have a different PKC (aPKC) than in Aplysia, but this may be due to aPKC having evolved after the split (needs to be tested). Dopamine, in Drosophila may be used for regulation, not convergence. This would entail some hypotheses worth testing.

According to the RNAseq database, the adenylyl cyklase rutabaga is also expressed in the motor neurons where we think the plasticity for operant self-learning takes place. We know that mutations in the rut gene improve self-learning, excluding the hypotheiss that rut may be downstream of aPKC. However, Lorenzetti et al. found that their Aplysia AC in question was a type II AC, while rut is a type I AC. It is conceivable that removal of rut could free its ATP pool for the type II AC and improve learning.
At the same time, it may be that this type II AC is downstream of a D2 receptor receiving input from the MBs inhibiting this AC, leading to inhibited self-learning while predictive colors are present. Imaging cAMP in these neurons would help us test this hypothesis.
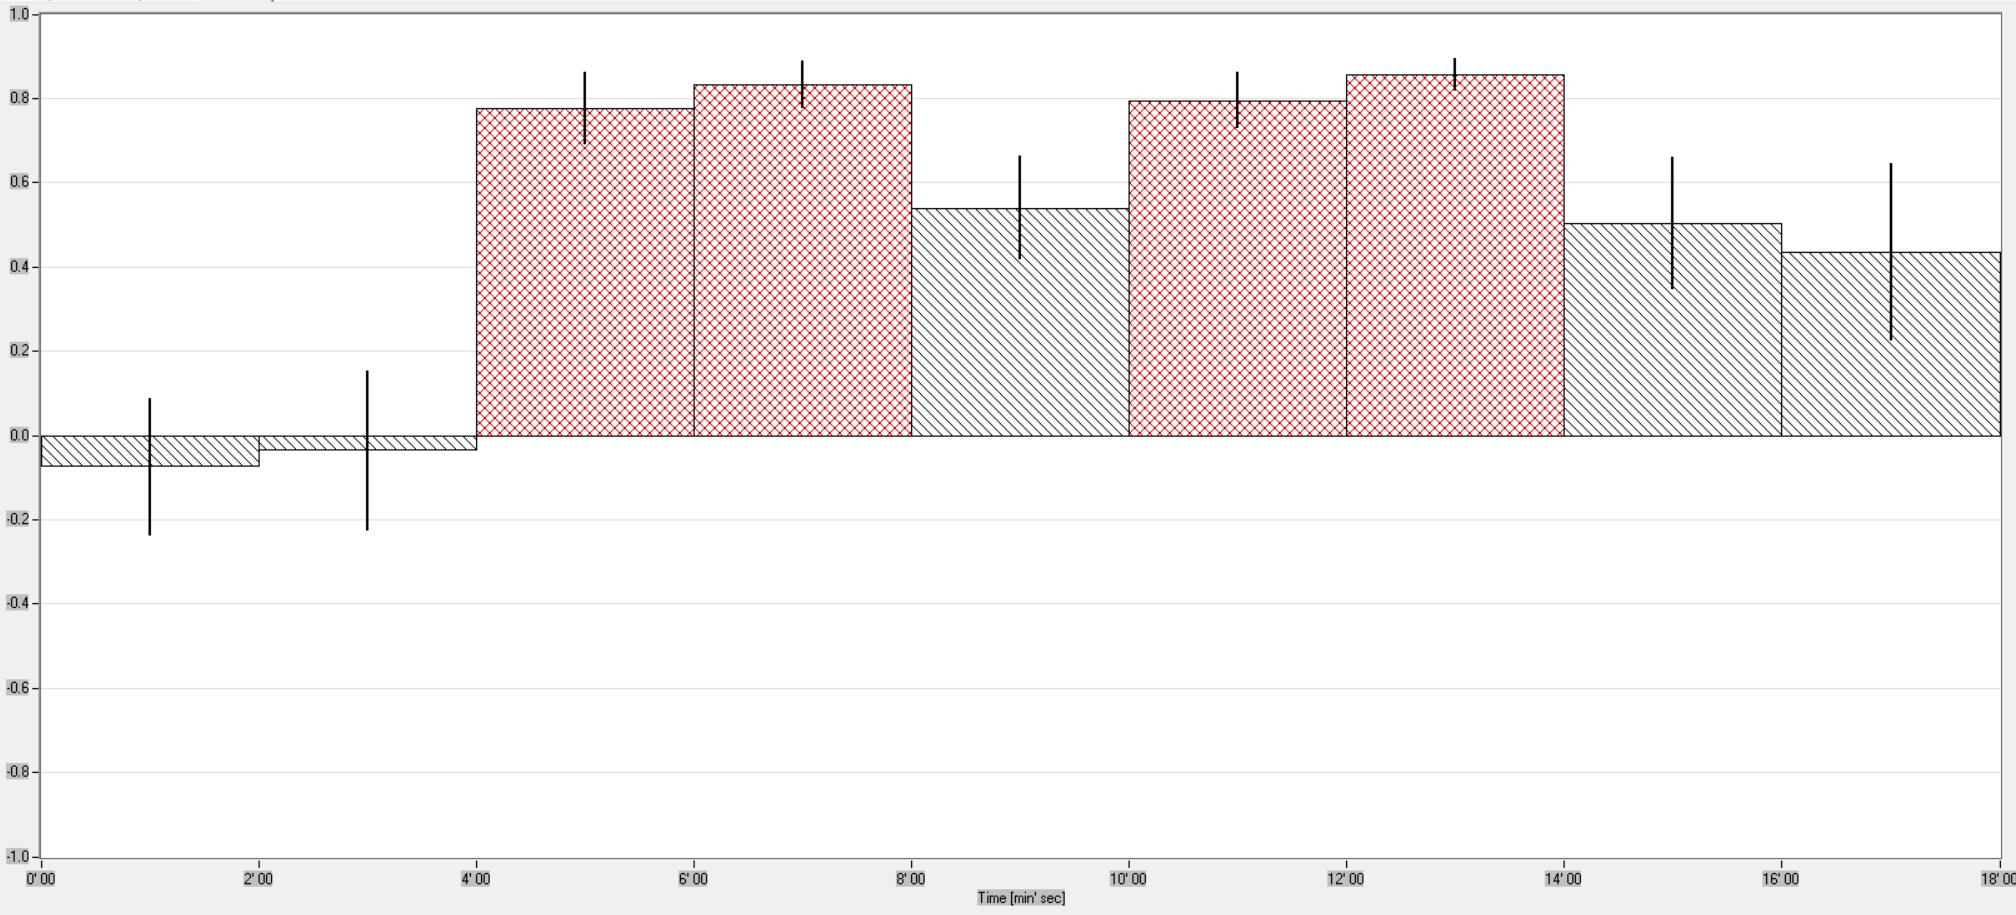
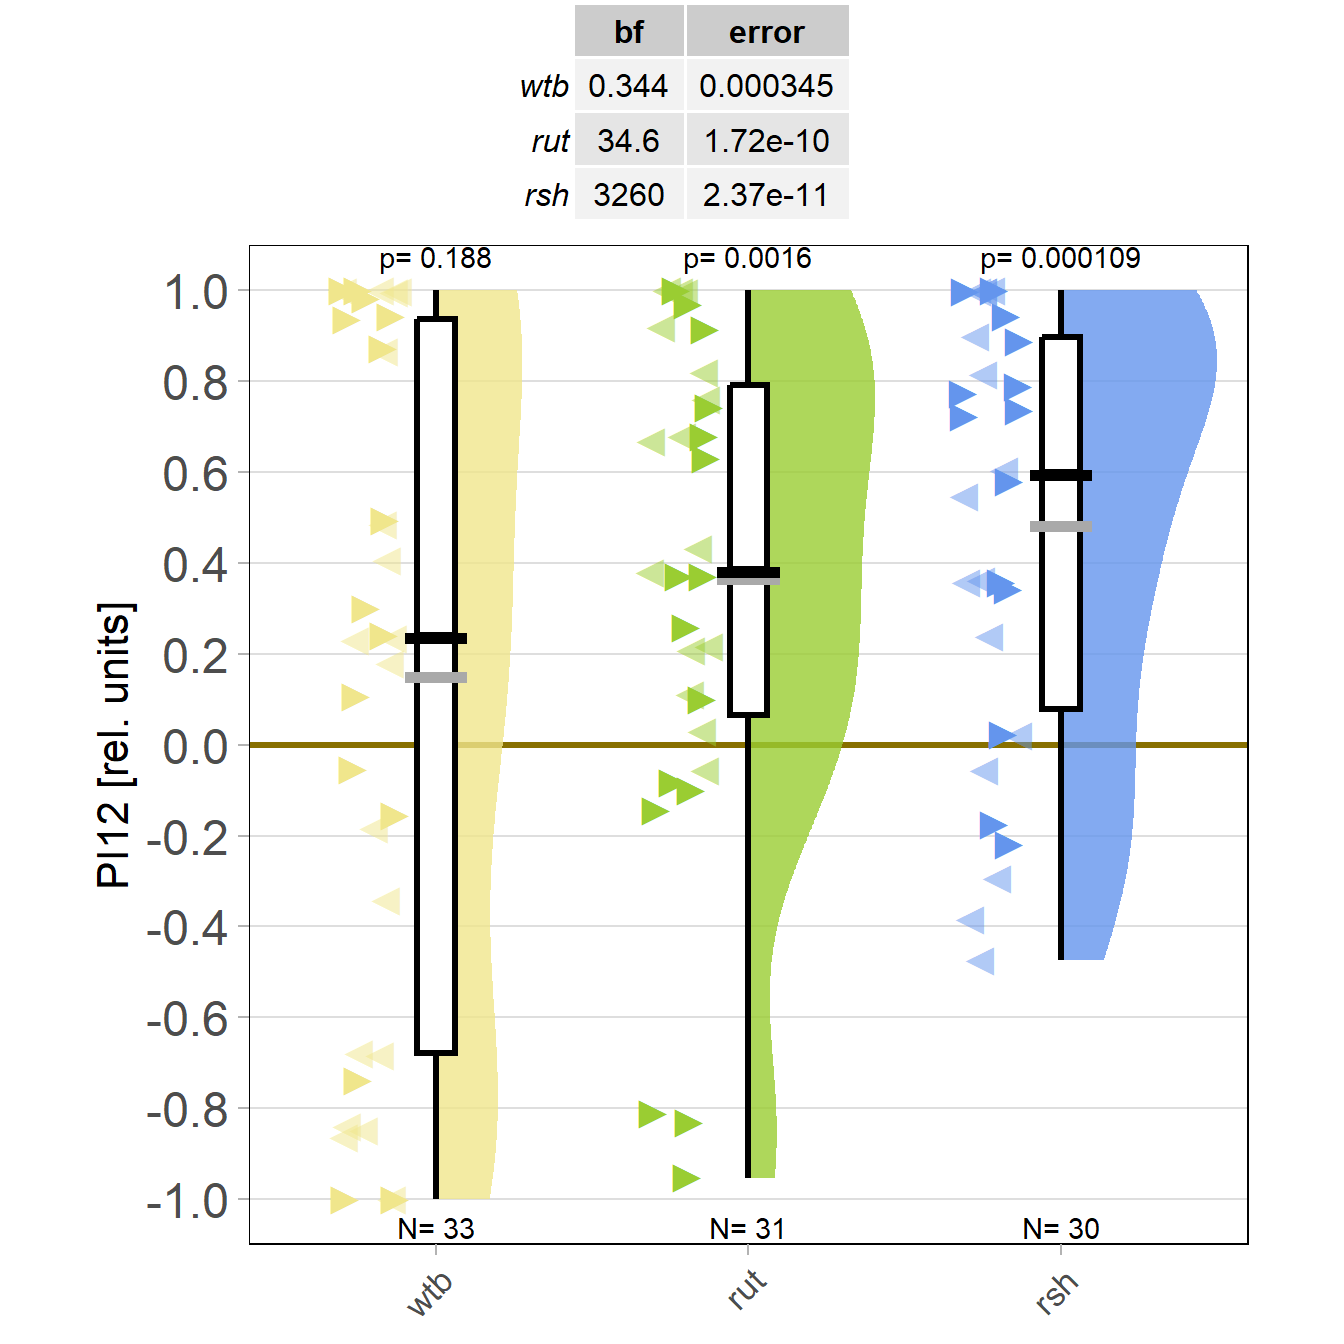
Alternatively, hypothetically, aPKC may be downstream of an inhibitory cAMP pathway, perhaps via rut, such that rut mutation would lead to improved self-learning and rut activation via D1 receptors would inhibit self-learning. This is not impossible, as rut mutant flies show premature habit formation (N=30):

In fact, radish shows the same phenotype (N=13):
So we need a hypothesis that explains these findings:
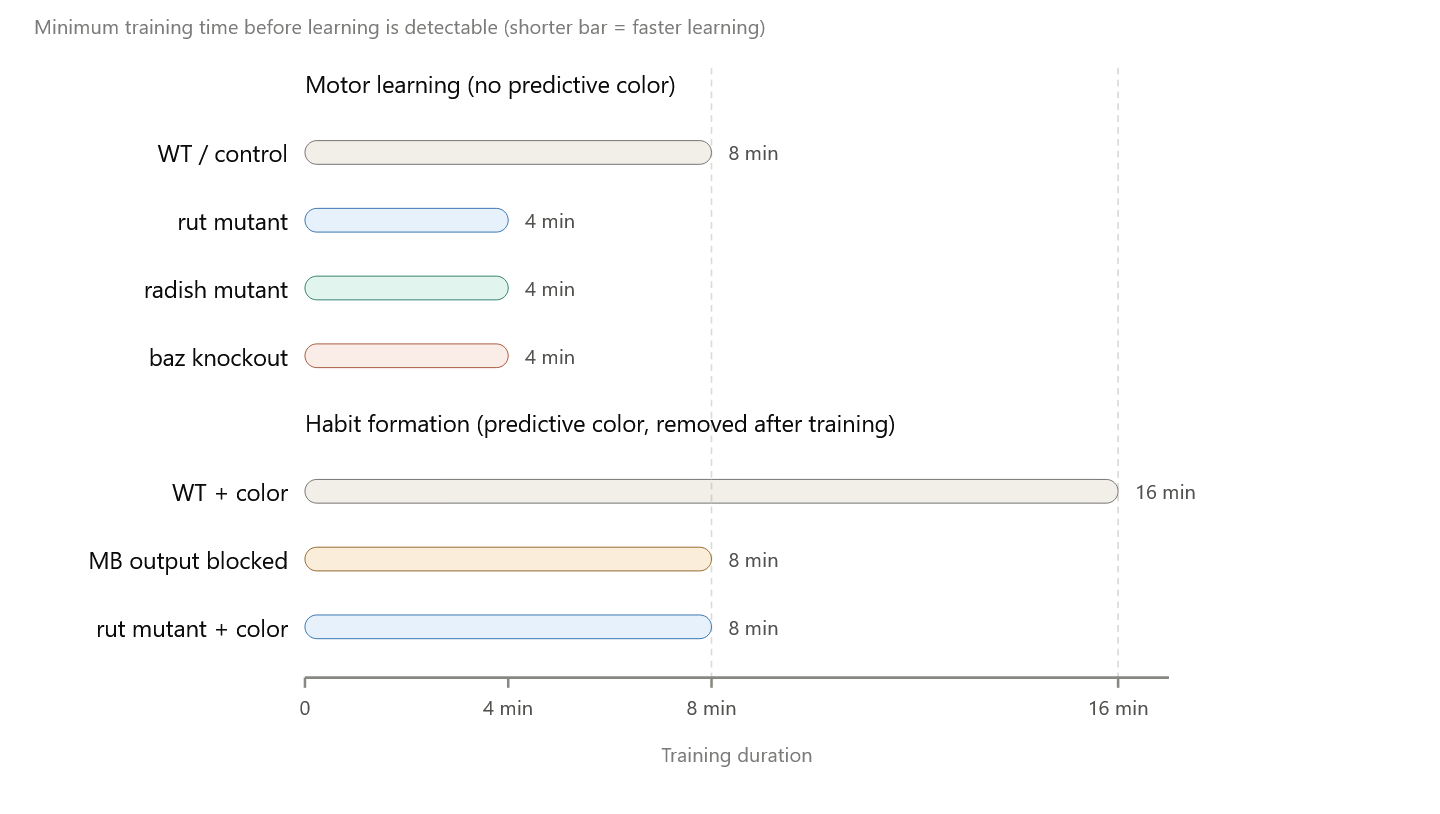
The rutabaga and radish genes inhibit self-learning (only 4 minutes training in mutants or 8 minutes with colors)
The mushroom-bodies inhibit self-learning when predictive colors are present (16 minutes training with colors)
In general, this is the problem we are trying to solve:
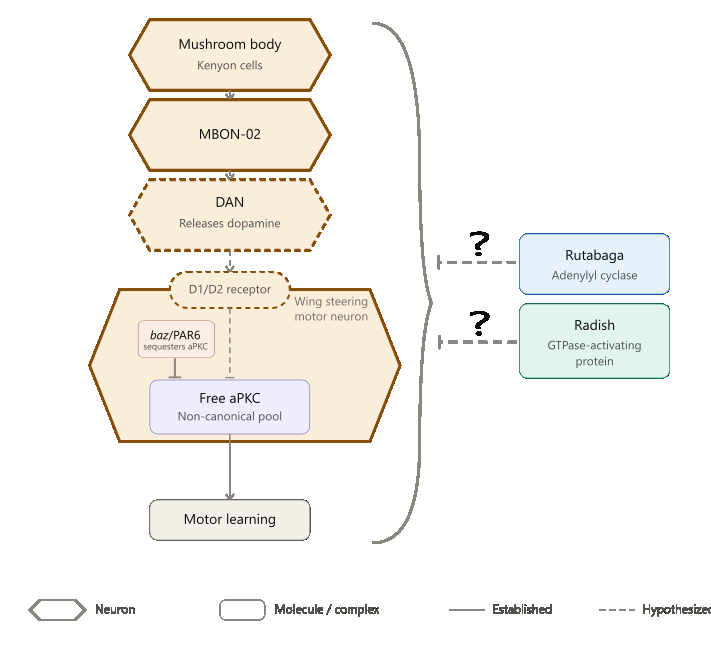
One way to test this is to do double manipulations of any of these individual ones. Another could be to quantify aPKC activity in some way. Overexpress dunce in FoxP neurons? Or wait for Julias project to give us some clues. What else?
Overview of results (maybe not complete?):
Category: Habit formation, MBON, operant self-learning, PKC | No Comments
Starting it back up
on Monday, December 11th, 2023 11:34 | by Björn Brembs
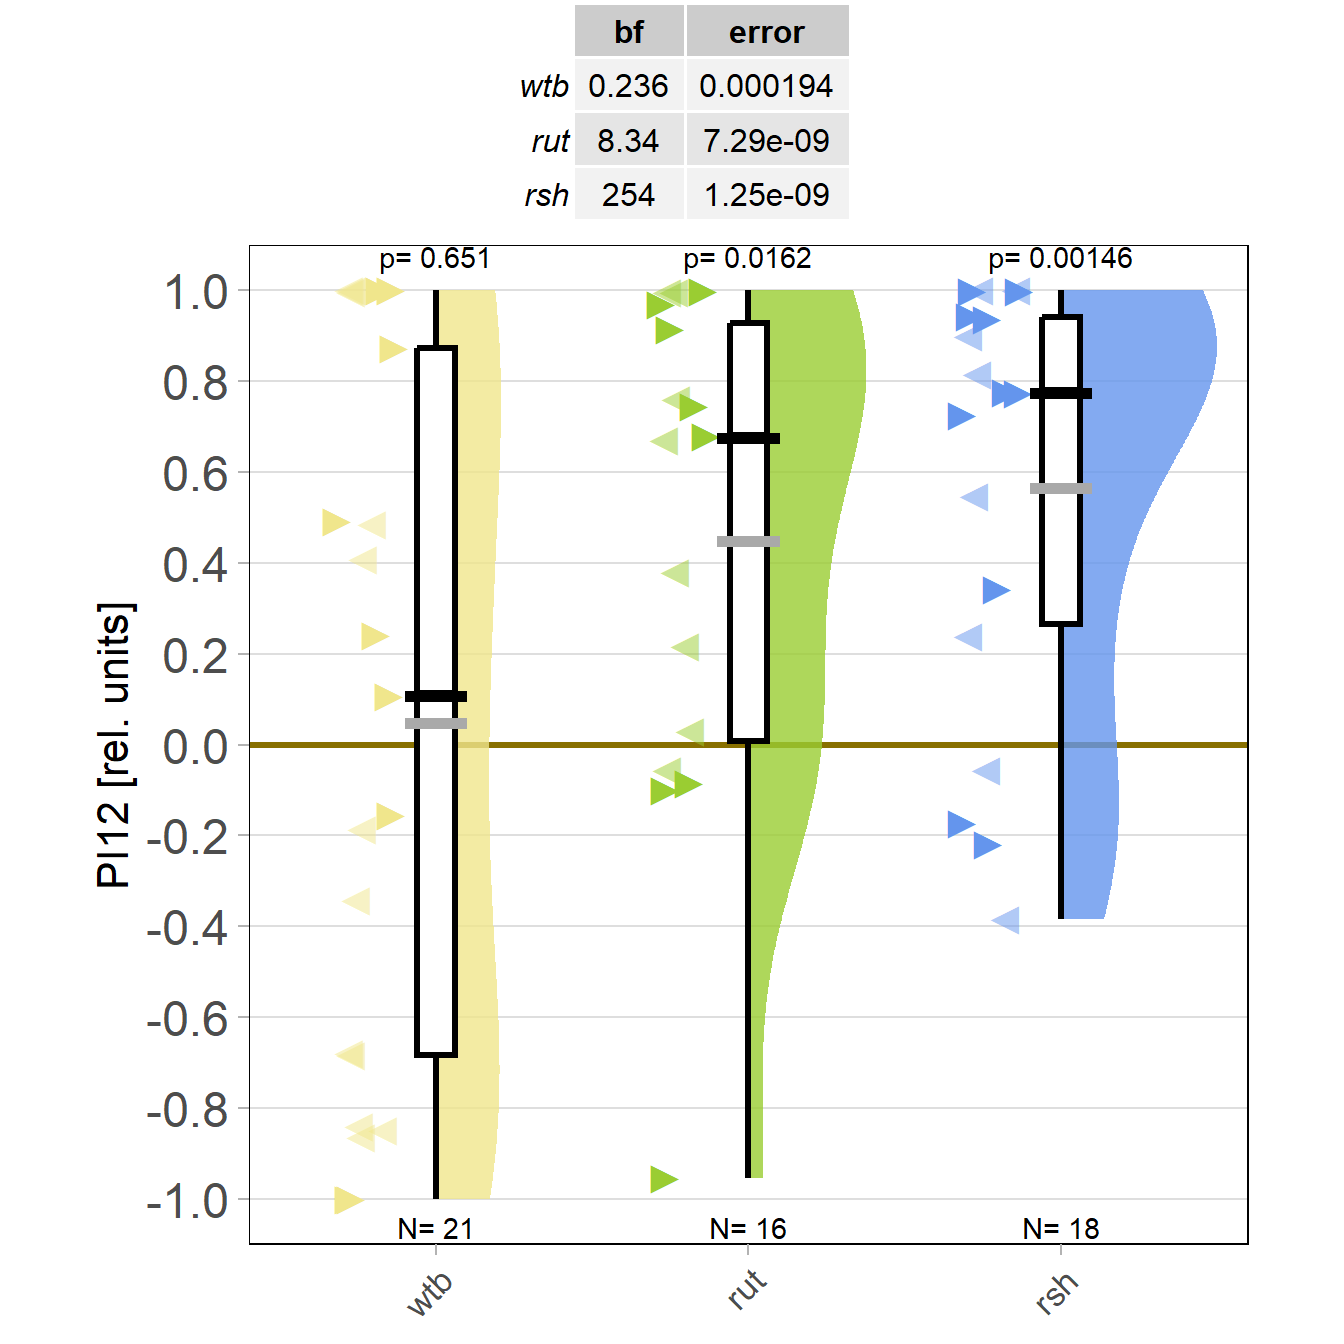
Last week, the torque mete ran for two days and I managed to record a few radish flies:
Category: Operant learning, operant self-learning | No Comments
Slowly collecting the mutants
on Friday, October 13th, 2023 6:13 | by Björn Brembs
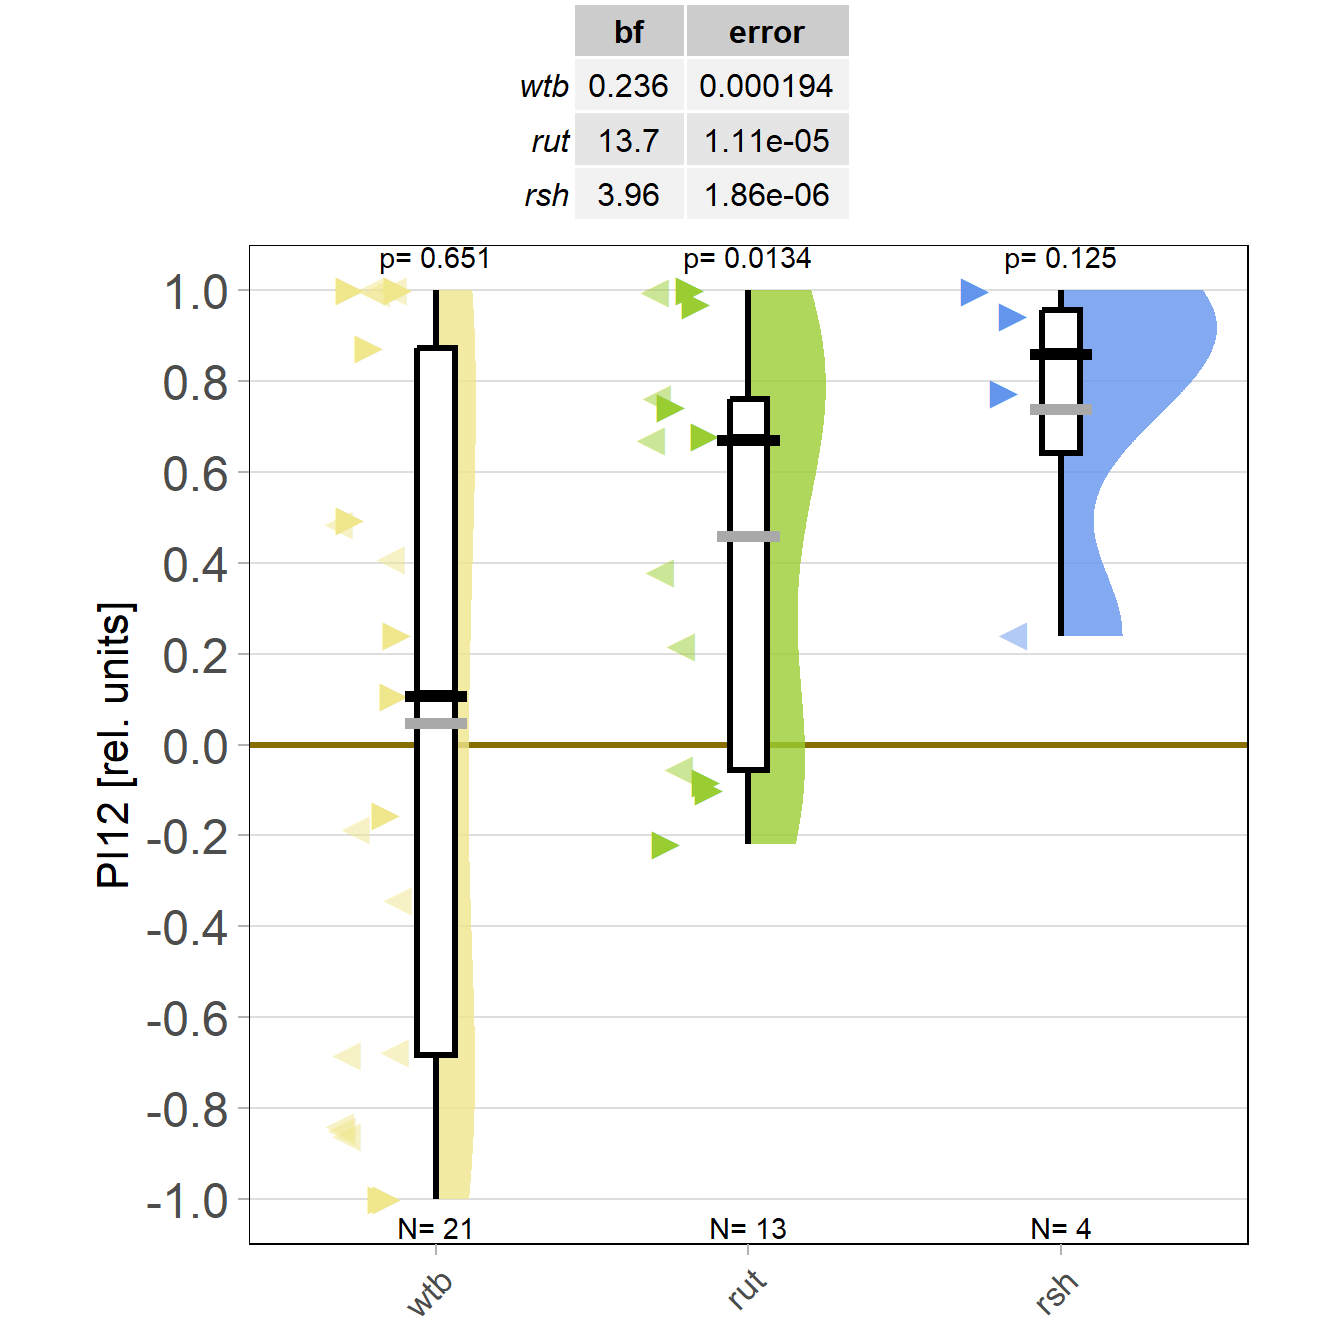
Finally, thanks to Marcella gluing to fly wheels instead of one, the mutant data are starting to roll in on the shortened self-learning experiment:
Category: Operant learning, operant self-learning | No Comments
Four minutes not enough
on Friday, September 29th, 2023 4:20 | by Björn Brembs
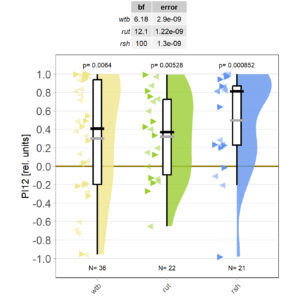
Eight minutes of yaw torque training work just fine for both wild type and mutant flies:
Reducing the training to four minutes is not enough for wild type flies:
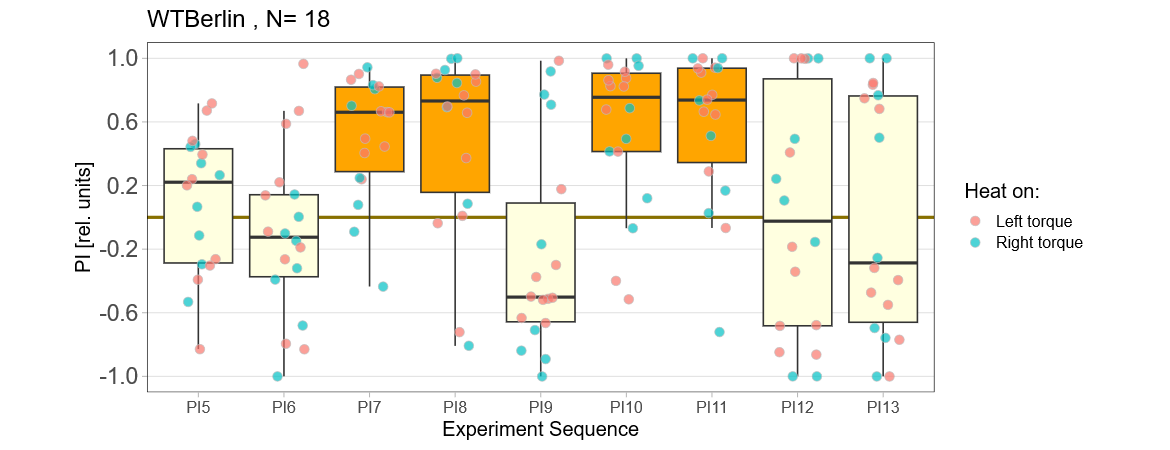
Now it will be exciting to see if the mutants still do what they did many years ago: learn better than wild type.
Category: Operant learning, operant self-learning | No Comments
Little by little
on Monday, July 24th, 2023 1:59 | by Björn Brembs
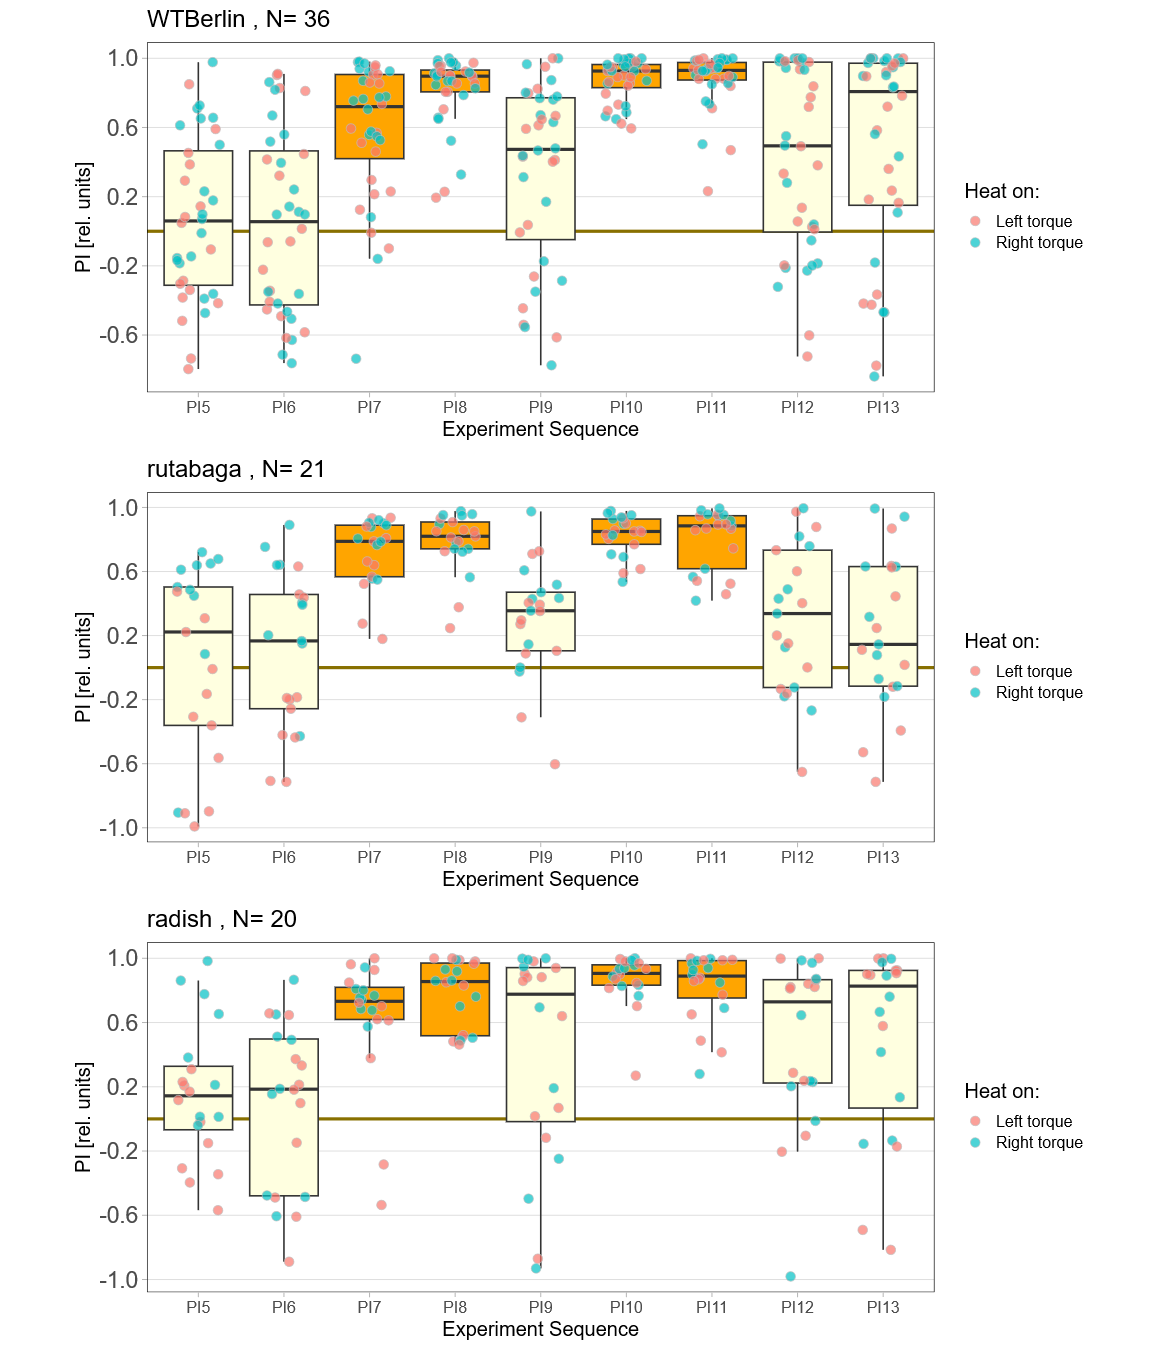
Despite very warm weather, some flies did fly, even though the learning performance of the control flies was really poor. At least for now, it looks like all stocks are learning and that rut and rsh flies learn at least equally well as the Berlin flies. I’ve also managed to fix the positive preference problem:
Category: operant self-learning, Radish | No Comments
Creating gRNAs via PCR
on Friday, July 7th, 2023 6:38 | by Isabel Stark
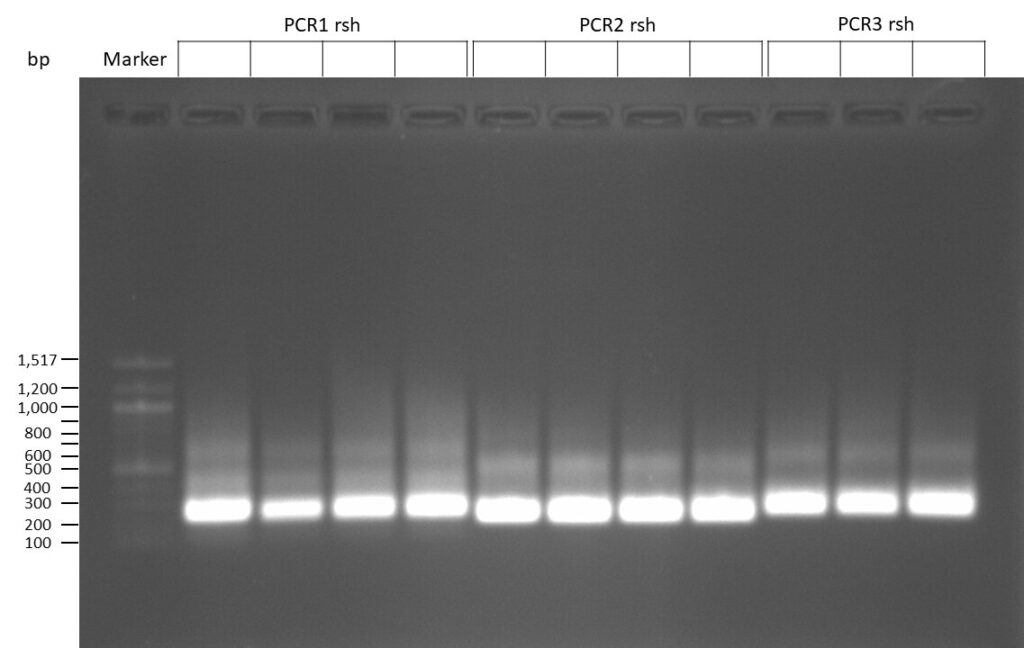
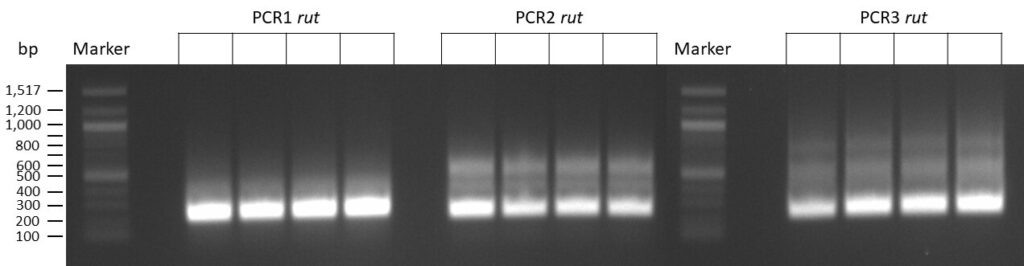
The template pCFD6 was used with a concentration of 640 pg/µl.
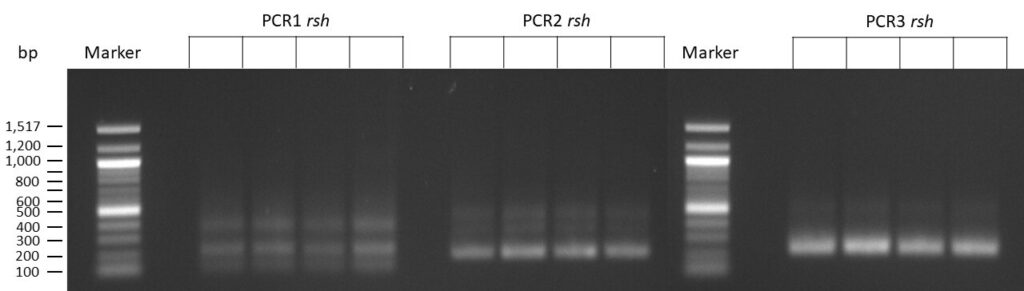
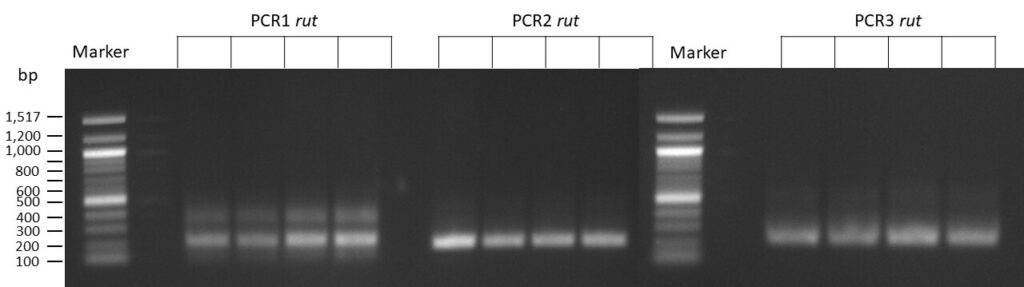
The template pCFD6 was used with a concentration of 64 pg/µl (1:10 dilution).
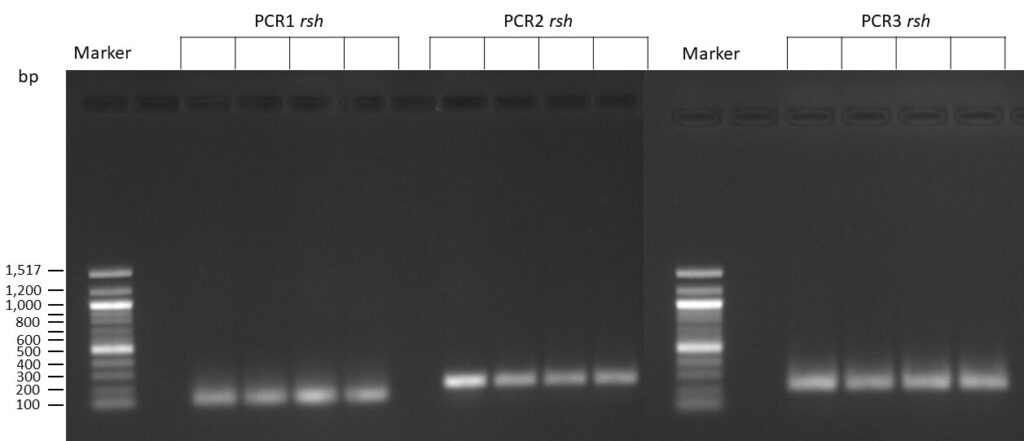
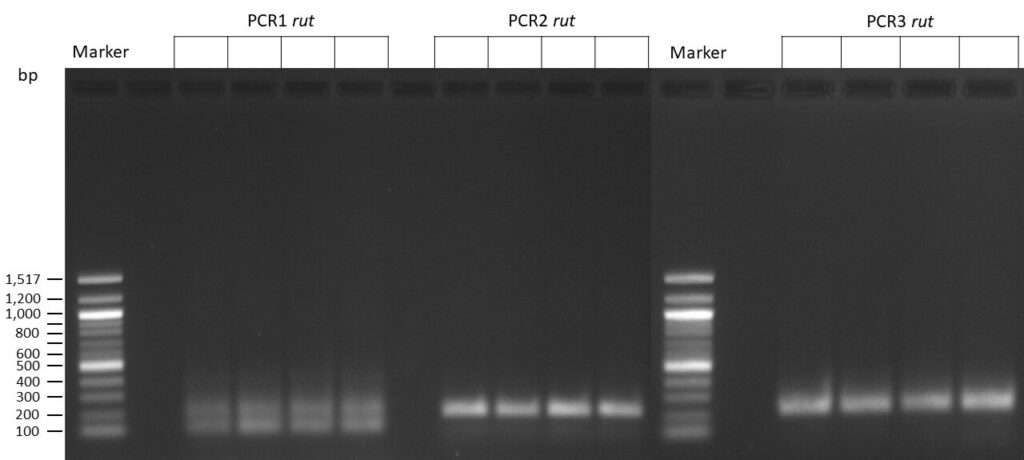
The template pCFD6 was used with a concentration of 64 pg/µl (1:10 dilution).
50µl of 5xQ5 High GC Enhancer was added to the PCR mix.
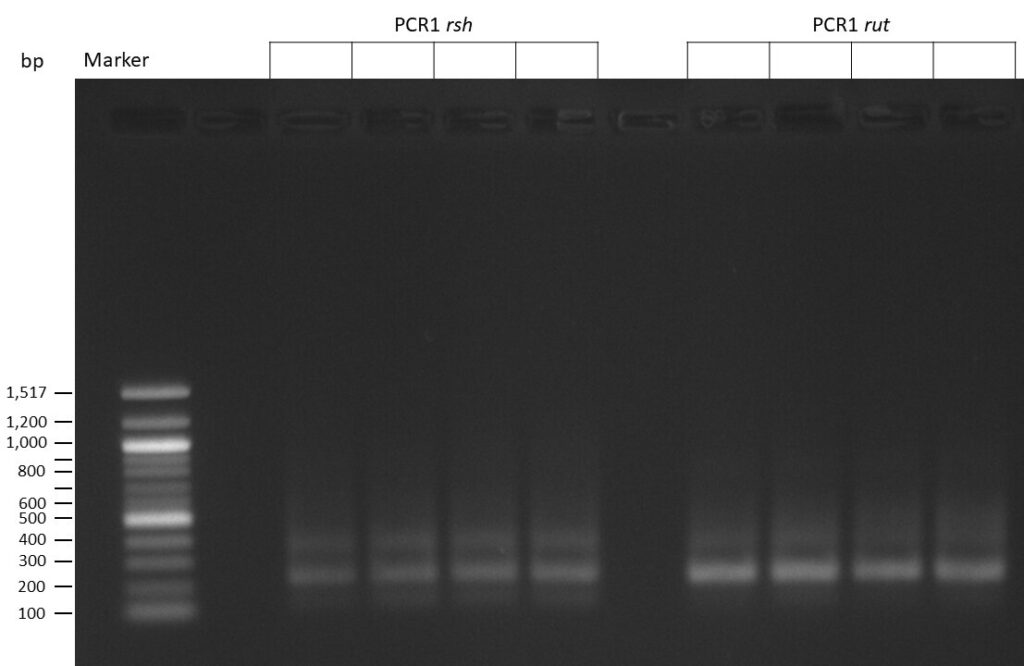
The template pCFD6 was used with a concentration of 128 pg/µl (1:5 dilution).
50µl of 5xQ5 High GC Enhancer was added to the PCR mix.
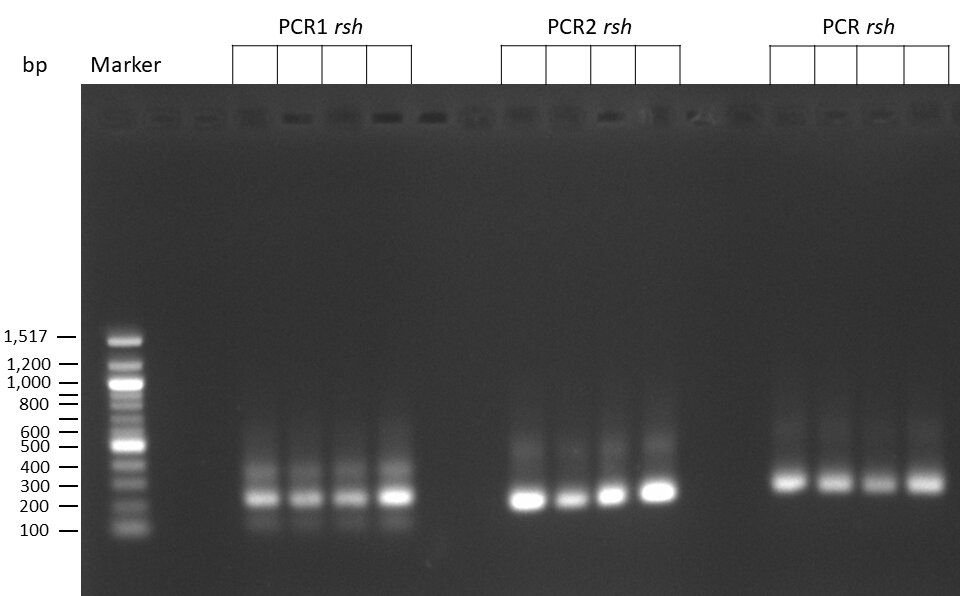
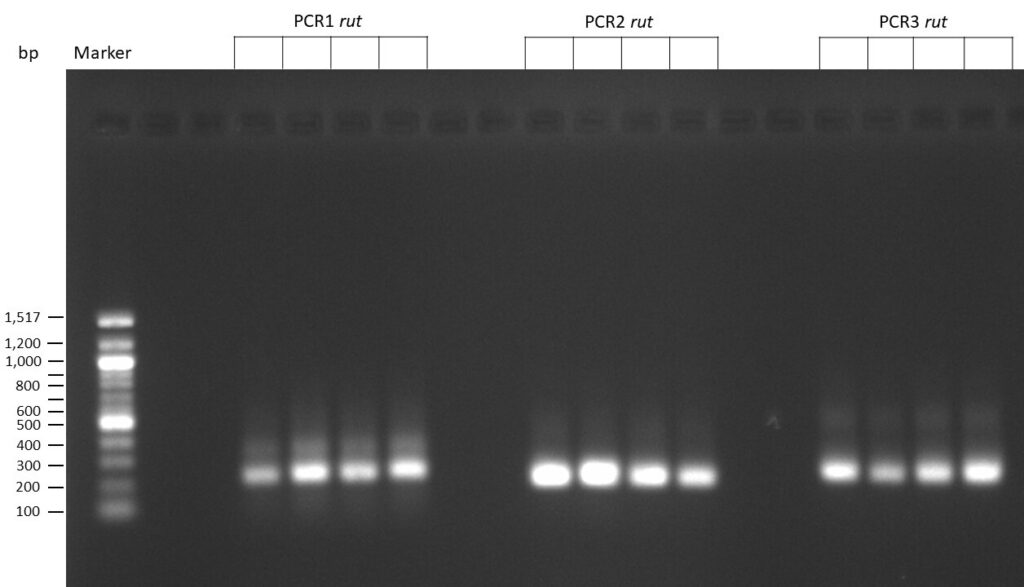
The template pCFD6 was used with a concentration of 640 pg/µl.
The Phusion DNA Polymerase was used instead of the Q5 High-Fidelity DNA Polymerase.
Category: genetics, Memory, Operant learning, operant self-learning, Radish, Uncategorized | No Comments
It’s a start
on Friday, June 16th, 2023 4:42 | by Björn Brembs
The first few rutabaga and radish mutants have been measured and so far it looks good: standard duration yaw torque learning – the situation all three groups should learn.

Category: Operant learning, operant self-learning | No Comments